Results and Demonstrations
Expressive Avatar Generation
SyncDreamer produces expressive talking avatars from a single reference image and speech audio, capturing emotion and natural head motion while maintaining identity.
Singing Avatar Generation
SyncDreamer enables singing avatar generation by capturing fine-grained audio dynamics, producing temporally synchronized motion that reflects musical rhythm, pitch variation, and expressive performance.
Robustness to Audio Variability
SyncDreamer demonstrates strong robustness to variations in audio characteristics such as rhythm, energy, and speaker identity. Using the same reference image, our model produces synchronized and expressive motion that adapts naturally to each unique input voice.
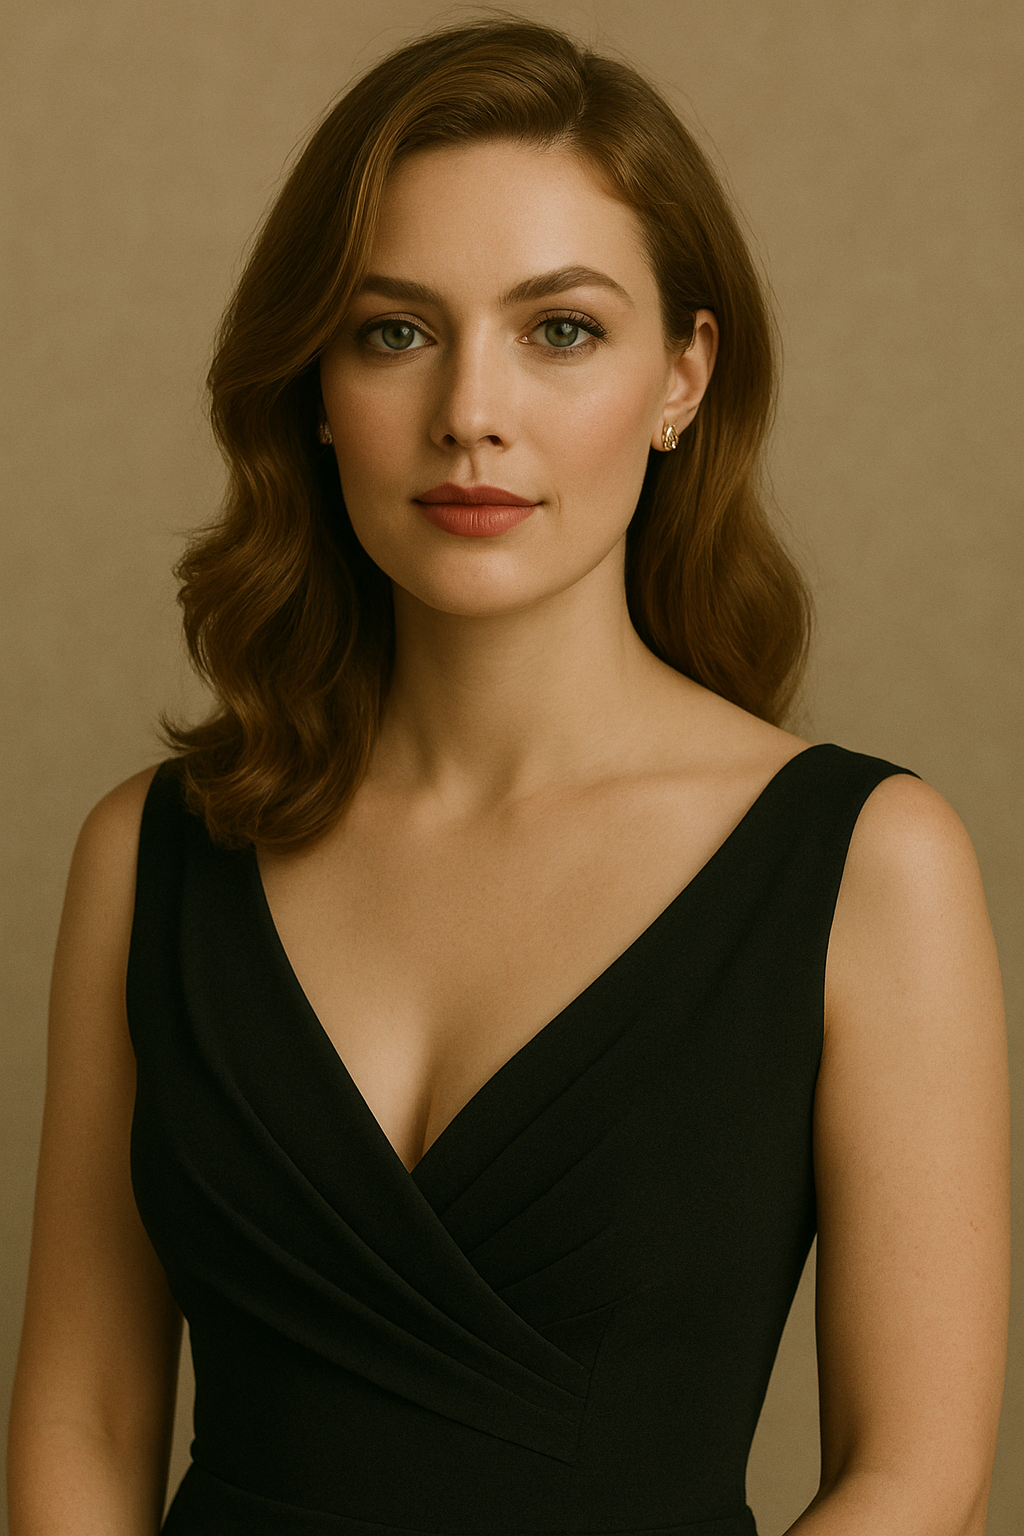
Reference ID